Utility of Word Embeddings in Language Identification
1. Overview
How it started
I was going through qdrant's UI after loading a dataset comprised of quranic text when I noticed something interesting, the datapoints can be distinguished by language through eye-ball inspection of a 2-D plot. qdrant's UI allows the querying of datapoints by their attributes and displaying the queried data in a 2-D plot obtained through dimensionality reduction techniques configurable by the user. The pattern was noticeable for both word representations produced using a commercially available LLM and publicly available LLM which led to the following questions:
What’s the utility of the word representations in language identification?
Can the same level of accuracy in language identification be achieved using a heuristic?
Key Findings - A heuristic approach that uses regular expressions to detect languages based on the script used in the text obtains comparable (or better) recall and precision on language detection, to word vectors produced using nomic-embed-text-latest (nomic v1.5), nomic-embed-text-v2-moe:latest, and gemini-embedding-001. The results for nomic-embed-text-latest is especially surprising given that it is not multilingual and was developed primarily for English (en). The text used for the assessment uses script primarily associated with the language e.g. Ge’ez for Amharic, Arabic script for Arabic (ar) and this is a key factor in the outcome of the assessment. Although cross-validation on a reasonable sample (40% of entire data) has been used to ascertain consistency in results, a larger sample may reveal a different pattern. The choice of sample size was mainly dictated by memory constraints.
So What - In situations where language is primarily expressed in the script mainly associated with it, examining the characters in the text could be more sufficient than LLM based word representations in detecting the language in the text.
- For natural language tasks such as language identification non-commercial embedding models such as nomic-embed-text-v2-moe:latest could be more suitable than commercially available embedding models such as gemini-embedding-001, given how much better it performed on this task: nomic-embed-text-v2-moe:latest outperformed gemini-embedding-001 on every metric in this assessment.
To address the two questions (above), I adopted the following approach:
Word embeddings and their corresponding text and attributes were sampled from three collections on qdrant where each collection corresponds to vectors produced using either gemini-embedding-001, nomic-embed-text-latest, or nomic-embed-text-v2-moe:latest. The text consists of quranic script in a variety of languages obtained from tanzil.net. Details of the text data and the LLMs is provided in Section 2.0.
To enable like-for-like comparison between the vectors, samples were first collected from one collection and the text from the collection was used to obtain a matching sample for each of the other collections i.e. the only thing that differs between the three collections is their word vectors (word embeddings).
For each sample from the collections, a UMAP model was fitted on a subset of the sample i.e. the training set, obtaining a projection of the data on a 2-dimensional Riemannian manifold. PCA was first used to reduce the dimensions of the vectors before fitting the UMAP model. Subsequently a knn-classifier is fitted on the projected data, assigning a label (predicted language) to each record. This is similar to the BERTopic approach.
The performance of each umap+knn-classifier in language identification was compared to a heuristic approach that uses the count of characters in the text associated with specific languages for language identification. The heuristic uses regular expressions in counting the characters and it is described in detail in Section 6.1.
flowchart LR

A[word embeddings] -->|sampling| B[sample]
B -->|UMAP - Dimensionality Reduction| D[Projections]
D --> |KNN Classification| E[Language Classification]
B -->|Heuristic Language Classification|F[Language Classification]
F-->|Metrics Calculation|G[Results Comparison]
E-->|Metrics Calculation|G
2.0 Data
The vectorised quranic text obtained from tanzil.net is stored in the following collections on a qdrant instance running locally on a homelab cluster. Details of each collection and the vectorisers used is provided below:
A list of the languages covered in this study and whether or not they are supported by either of the embedding models is provided below
Code
Language
gemini-embedding-001
nomic v1.5 (nomic-embed-text-latest)
nomic-embed-text-v2-moe
am
Amharic
✓
✗
✓
ar
Arabic
✓
✗
✓
bs
Bosnian
✓
✗
✓
dv
Divehi
✓
✗
✗
en
English
✓
✓
✓
es
Spanish
✓
✗
✓
fa
Persian
✓
✗
✓
ha
Hausa
✓
✗
✓
nl
Dutch
✓
✗
✓
ru
Russian
✓
✗
✓
sd
Sindhi
✓
✗
✗
so
Somali
✓
✗
✓
sq
Albanian
✓
✗
✓
ta
Tamil
✓
✗
✓
tg
Tajik
✓
✗
✓
th
Thai
✓
✗
✓
tr
Turkish
✓
✗
✓
ur
Urdu
✓
✗
✓
uz
Uzbek
✓
✗
✓
zh
Chinese
✓
✗
✓
2.1 Sampling
Samples were collected from the collections starting with one collection first and then using the text in the first collection to sample records matching the same text from the other two collections.
The data is largely comprised of text in English (en) therefore some downsampling was applied to prevent skewing the results.
Code
def downsample_majority(df,samp_col="language"): props = df.groupby([samp_col]).size().to_dict() sorted_props =sorted(props, key=lambda e:props[e],reverse=True) maj = sorted_props[0] avg_minority =int(np.ceil(np.mean([props[e] for e in props if e!=maj]))) A = df[df[samp_col].eq(maj)].sample(avg_minority) B = df[~df[samp_col].eq(maj)] C = pd.concat([A,B]).reset_index(drop=True)return C
An example of attributes of vectors sampled from the collection corresponding to gemini-embedding-001 is shown below. The column text in the table is what the vectors were generated from.
Code
samples[init].head()
index
id
language
name
chapter
verse
text
surah_name
revelation_order
revelation_type
revelation_note
language_description
0
203498
d10bf675-917c-590b-a5b1-579a286546df
en
hilali
12
62
And [Yusuf (Joseph)] told his servants to put ...
Yusuf
53
Meccan
Except 1, 2, 3, 7, from Medina
English
1
52727
36202e3a-29fd-585e-a4fc-0be6a48eb049
en
itani
2
223
Your women are cultivation for you; so approac...
Al-Baqara
87
Medinan
Except 281 from Mina at the time of the Last Hajj
English
2
54352
37c344fb-1a90-5da1-8389-8604c427da82
en
arberry
78
2
Of the mighty tiding
An-Naba
80
Meccan
NaN
English
3
86554
58ac7315-6d1a-5296-aa16-649a3faa1149
en
arberry
5
70
And We took compact with the Children of Israe...
Al-Maaida
112
Medinan
Except 3, revealed at Arafat on Last Hajj
English
4
25736
1a613a70-8676-5b60-8976-c3fd3b0c6dc4
en
ahmedraza
10
74
Then after him, We sent other Noble Messengers...
Yunus
51
Meccan
Except 40, 94, 95, 96, from Medina
English
A sample equivalent to that collected from quran-embedding-prefect-gemini-embedding-001 was collected from the other two collections detailed in Section 2.0
Code
filter_columns = ['language','name','chapter','verse','text']colls = [coll for coll in collections if coll !=init]for c in colls:if collections[c]!=None:print("Processing {}".format(c)) matching_records = fetch_records_for_dataframe( samples[init], collections[c], filter_cols = filter_columns, batch_size =200, with_vectors =True ) samp, vec = extract_payload(matching_records, exclude=[]) samples[c] = pd.DataFrame(samp) vectors[c] = vecassertlen(samples[c]) ==len(samples[init]), (f"{c}: expected {len(samples[init])} matching records, got {len(samples[c])} ""- some rows had no exact match, so the like-for-like comparison ""across collections no longer holds." )else: samples[c] =None vectors[c] =None
An example of attributes of sample records stored in quran-embedding-prefect-nomic-embed-text-latest is shown below
Code
samples['nomic-embed-text:latest'].head()
id
language
name
chapter
verse
text
surah_name
revelation_order
revelation_type
revelation_note
0
d10bf675-917c-590b-a5b1-579a286546df
en
hilali
12
62
And [Yusuf (Joseph)] told his servants to put ...
Yusuf
53
Meccan
Except 1, 2, 3, 7, from Medina
1
36202e3a-29fd-585e-a4fc-0be6a48eb049
en
itani
2
223
Your women are cultivation for you; so approac...
Al-Baqara
87
Medinan
Except 281 from Mina at the time of the Last Hajj
2
37c344fb-1a90-5da1-8389-8604c427da82
en
arberry
78
2
Of the mighty tiding
An-Naba
80
Meccan
NaN
3
58ac7315-6d1a-5296-aa16-649a3faa1149
en
arberry
5
70
And We took compact with the Children of Israe...
Al-Maaida
112
Medinan
Except 3, revealed at Arafat on Last Hajj
4
1a613a70-8676-5b60-8976-c3fd3b0c6dc4
en
ahmedraza
10
74
Then after him, We sent other Noble Messengers...
Yunus
51
Meccan
Except 40, 94, 95, 96, from Medina
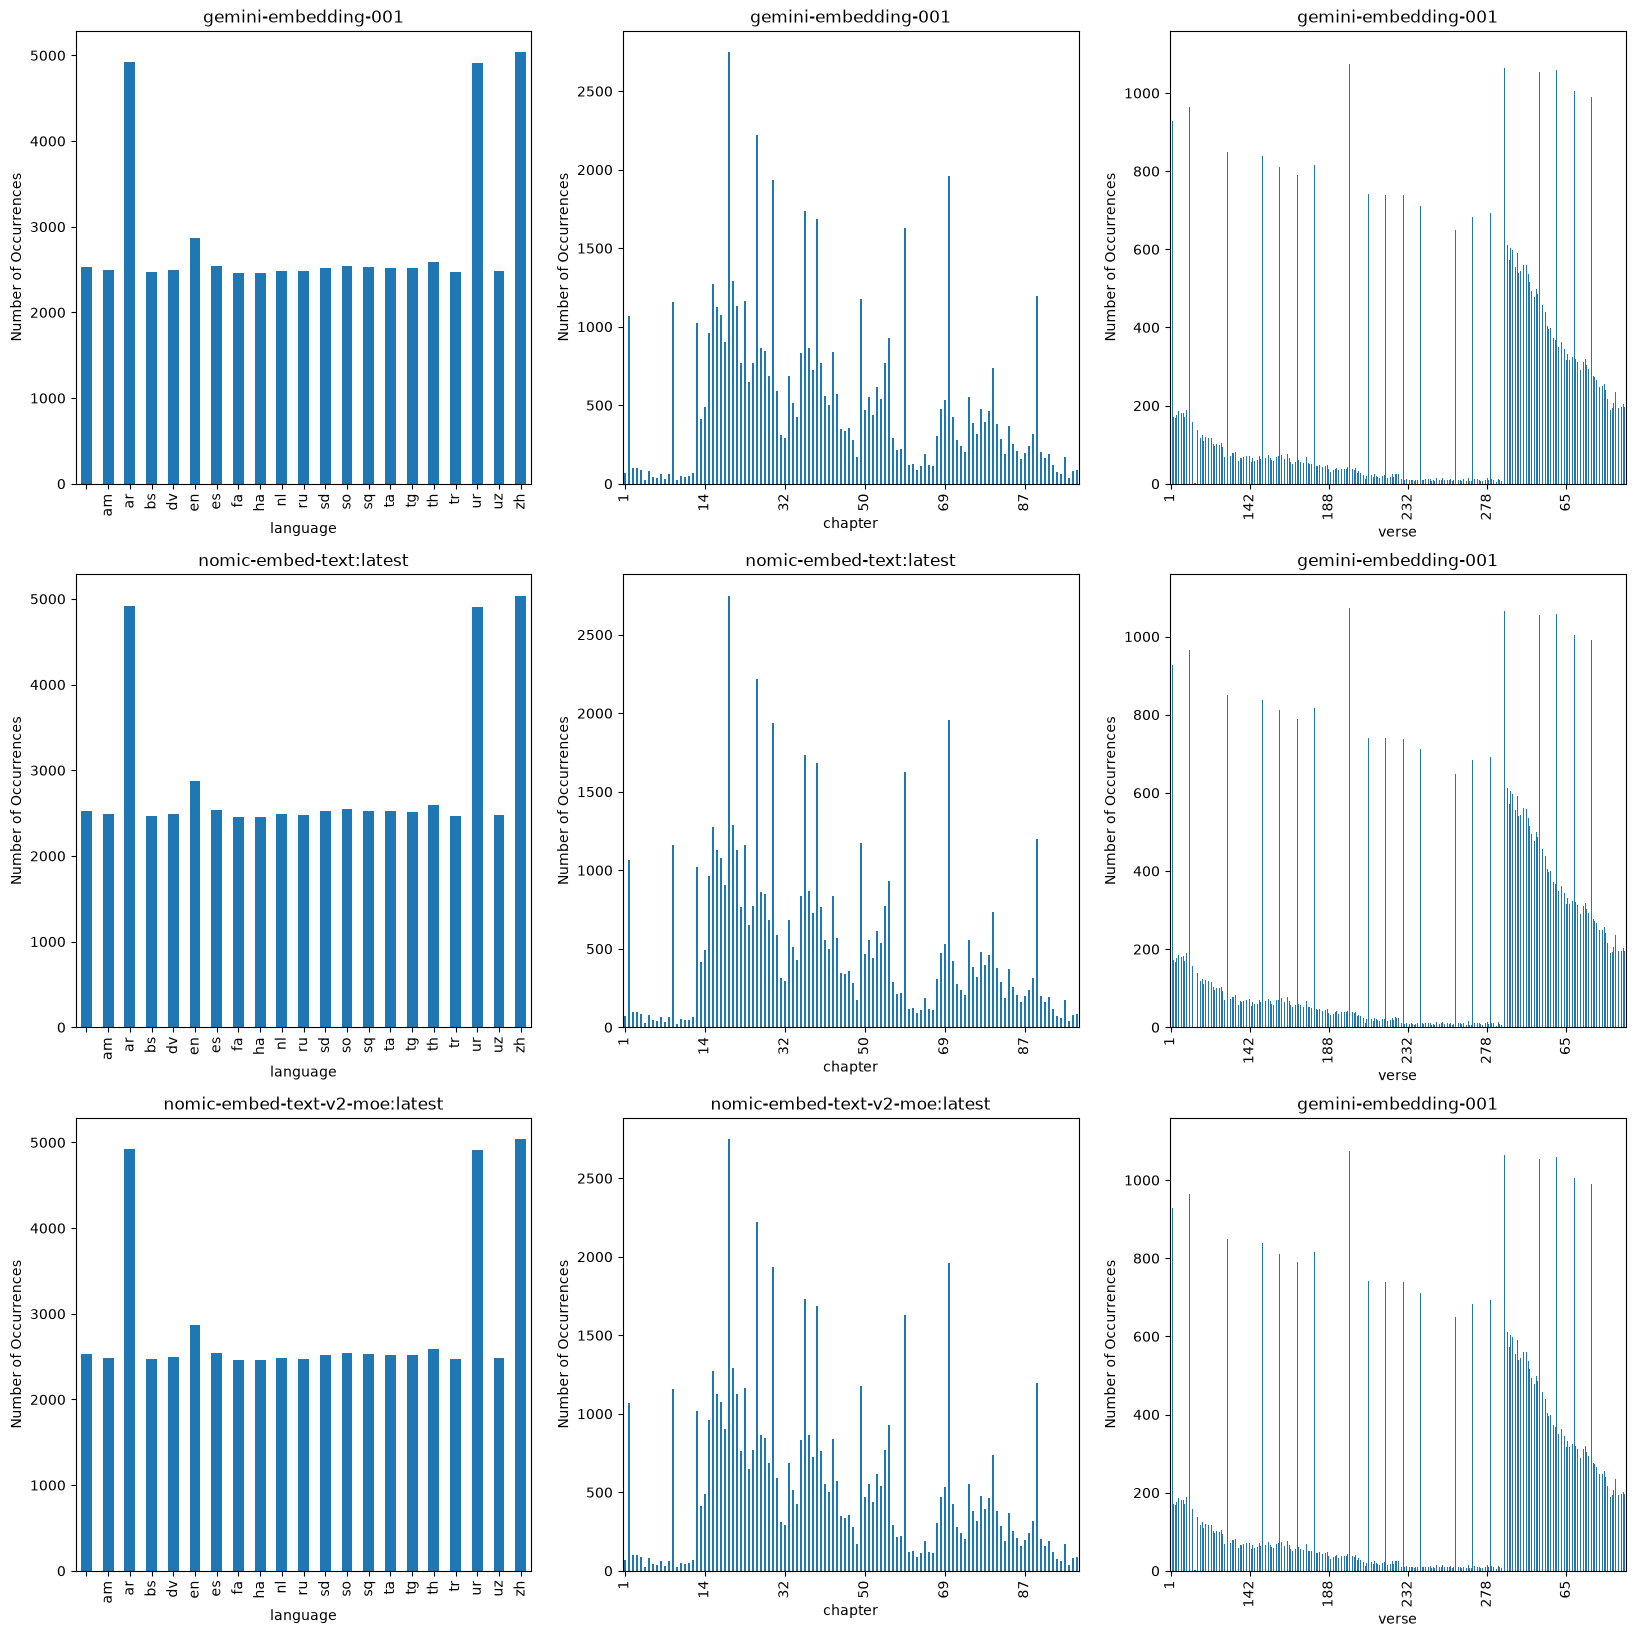
A comparison of the statistical signature of the sample from the collection associated with gemini-embedding-001 to collections associated with the other models is shown below. The figure shows that the samples are equivalent i.e. the text, chapter, and verse match across the three samples.
Code
fig, ax = plt.subplots(3,3,figsize=(20,20), sharex=False)ax = ax.flatten()for x,c inzip([0, 3, 6],collections.keys()): samples[c].groupby('language').size().plot.bar(ax=ax[x]) ax[x].set_title(c)for x,c inzip([1,4,7],collections.keys()): samples[c].groupby('chapter').size().plot.bar(ax=ax[x]) ax[x].xaxis.set_major_locator(ticker.MaxNLocator(nbins=6)) ax[x].set_title(c)for x,c inzip([2,5,8],collections.keys()): samples[init].groupby('verse').size().plot.bar(ax=ax[x]) ax[x].xaxis.set_major_locator(ticker.MaxNLocator(nbins=6)) ax[x].set_title(init)for a in ax: a.set_ylabel("Number of Occurrences")
Code
for col in samples:if collections[col]!=None: samples[col]['language_description'] = samples[col]['language'].map(language_map)
Code
counts = {}for c in samples:if collections[c] !=None: count = samples[c].fillna('n/a').groupby(['language','language_description'],dropna=False).size() counts[c] = count
A comparison of the number of records in each sample is provided below. The sample is largely dominated by english scripts
3.0 Language Identification Using Word Representations
3.1 PCA + UMAP Parameters
The 768-dimensional vectors are first reduced with PCA before UMAP is fitted on the result - this cuts UMAP’s nearest-neighbor search cost substantially, since that cost scales with the input dimensionality. Details of the parameters used for the PCA step and the subsequent UMAP fit are provided below
def train_test_split(df, id_col="id", train_frac=0.7):""" split a dataframe into train and test based on id_col """ tr_id = df.sample(frac=train_frac, random_state=np.random.RandomState(123456))[id_col] tst_id = df[~df[id_col].isin(tr_id)][id_col] tr_flag = df.id.isin(tr_id) tst_flag = df.id.isin(tst_id)return tr_flag, tst_flagdef train_umap(vec, pca_kwargs=None, **kwargs):""" reduce dimensionality with PCA, then fit a umap model on the reduced vectors """ dim_model = Pipeline([ ('pca', PCA(**(pca_kwargs or {}))), ('umap', UMAP(**kwargs)), ]) dim_red = dim_model.fit_transform(vec)return dim_red, dim_modeldef fit_knn_classifier(red_vec,tr_tar,**kwargs):""" fit a knn classifier """ k_class = KNeighborsClassifier(**kwargs) k_class.fit(red_vec, tr_tar)return k_classdef build_pred_pipeline(dim_model, cls_model):""" build a pipeline using dim_model (the umap model) and cls_model (the knn model)""" pip_line = Pipeline([('dim_model',dim_model), ('cls_model',cls_model)])return pip_line
Code
def compute_norm_mutual_info(df,tar_col,pred_col):""" Computes the mutual information based on columns tar_col (target) and pred_col (prediction) """ tar = df[tar_col].to_numpy() pred = df[pred_col].to_numpy() mi = normalized_mutual_info_score(tar,pred)return mi
Code
def compute_recall(df,tar_col, pred_col,average="macro"):"""Calculates the recall based on tar_col (target) and pred_col (prediction) """ tar = df[tar_col].to_numpy() pred = df[pred_col].to_numpy() rec = recall_score(tar, pred,average=average,zero_division=np.nan)return rec
Code
def compute_precision(df, tar_col,pred_col,average="macro"):""" Calculates the precision based on tar_col (target) and pred_col (prediction) """ tar = df[tar_col].to_numpy() pred = df[pred_col].to_numpy() prec = precision_score(tar,pred, average=average,zero_division=np.nan)return prec
Code
def style_dataframe_heatmap( df: pd.DataFrame, cmap: str="YlGnBu", precision: int=2 ) -> Styler:"""Returns a pandas Styler with a background heatmap pinned strictly between 0 and 1."""return ( df.style.background_gradient(cmap=cmap, vmin=0.0, vmax=1.0) .format(f"{{:.{precision}f}}") .set_properties(**{"text-align": "center"}) )
Code
def style_summary_table( df: pd.DataFrame, cmap: str="Blues", vmin: float=0.0, vmax: float=1.0,) -> Styler:"""Applies a background gradient to all rows except the first row (e.g. 'Number of Languages'). """# First row is the count row (e.g. 'Number of Languages'); the rest are stats. count_row = df.index[0] stat_rows = df.index[1:] styled = ( df.style.background_gradient( cmap=cmap, vmin=vmin, vmax=vmax, subset=pd.IndexSlice[stat_rows, :], ) .format("{:.0f}", subset=pd.IndexSlice[[count_row], :]) .format("{:.2f}", subset=pd.IndexSlice[stat_rows, :]) .set_properties(**{"text-align": "center"}) )return styled
The samples are split into a train and test set for validation purposes and a UMAP model is fitted on the portion of the sample tagged as training
Processing gemini-embedding-001
UMAP(n_epochs=300, n_neighbors=30, verbose=True)
Sat Sep 12 17:15:01 2026 Construct fuzzy simplicial set
Sat Sep 12 17:15:01 2026 Finding Nearest Neighbors
Sat Sep 12 17:15:01 2026 Building RP forest with 15 trees
Sat Sep 12 17:15:07 2026 NN descent for 15 iterations
     1  /  15
     2  /  15
     3  /  15
    Stopping threshold met -- exiting after 3 iterations
Sat Sep 12 17:15:27 2026 Finished Nearest Neighbor Search
Sat Sep 12 17:15:32 2026 Construct embedding
    completed  0  /  300 epochs
    completed  30  /  300 epochs
    completed  60  /  300 epochs
    completed  90  /  300 epochs
    completed  120  /  300 epochs
    completed  150  /  300 epochs
    completed  180  /  300 epochs
    completed  210  /  300 epochs
    completed  240  /  300 epochs
    completed  270  /  300 epochs
Sat Sep 12 17:17:08 2026 Finished embedding
Processing nomic-embed-text:latest
UMAP(n_epochs=300, n_neighbors=30, verbose=True)
Sat Sep 12 17:17:11 2026 Construct fuzzy simplicial set
Sat Sep 12 17:17:11 2026 Finding Nearest Neighbors
Sat Sep 12 17:17:11 2026 Building RP forest with 15 trees
Sat Sep 12 17:17:11 2026 NN descent for 15 iterations
     1  /  15
     2  /  15
    Stopping threshold met -- exiting after 2 iterations
Sat Sep 12 17:17:20 2026 Finished Nearest Neighbor Search
Sat Sep 12 17:17:21 2026 Construct embedding
    completed  0  /  300 epochs
    completed  30  /  300 epochs
    completed  60  /  300 epochs
    completed  90  /  300 epochs
    completed  120  /  300 epochs
    completed  150  /  300 epochs
    completed  180  /  300 epochs
    completed  210  /  300 epochs
    completed  240  /  300 epochs
    completed  270  /  300 epochs
Sat Sep 12 17:25:18 2026 Finished embedding
Processing nomic-embed-text-v2-moe:latest
UMAP(n_epochs=300, n_neighbors=30, verbose=True)
Sat Sep 12 17:25:20 2026 Construct fuzzy simplicial set
Sat Sep 12 17:25:20 2026 Finding Nearest Neighbors
Sat Sep 12 17:25:20 2026 Building RP forest with 15 trees
Sat Sep 12 17:25:20 2026 NN descent for 15 iterations
     1  /  15
     2  /  15
     3  /  15
     4  /  15
    Stopping threshold met -- exiting after 4 iterations
Sat Sep 12 17:25:32 2026 Finished Nearest Neighbor Search
Sat Sep 12 17:25:33 2026 Construct embedding
    completed  0  /  300 epochs
    completed  30  /  300 epochs
    completed  60  /  300 epochs
    completed  90  /  300 epochs
    completed  120  /  300 epochs
    completed  150  /  300 epochs
    completed  180  /  300 epochs
    completed  210  /  300 epochs
    completed  240  /  300 epochs
    completed  270  /  300 epochs
Sat Sep 12 17:27:18 2026 Finished embedding
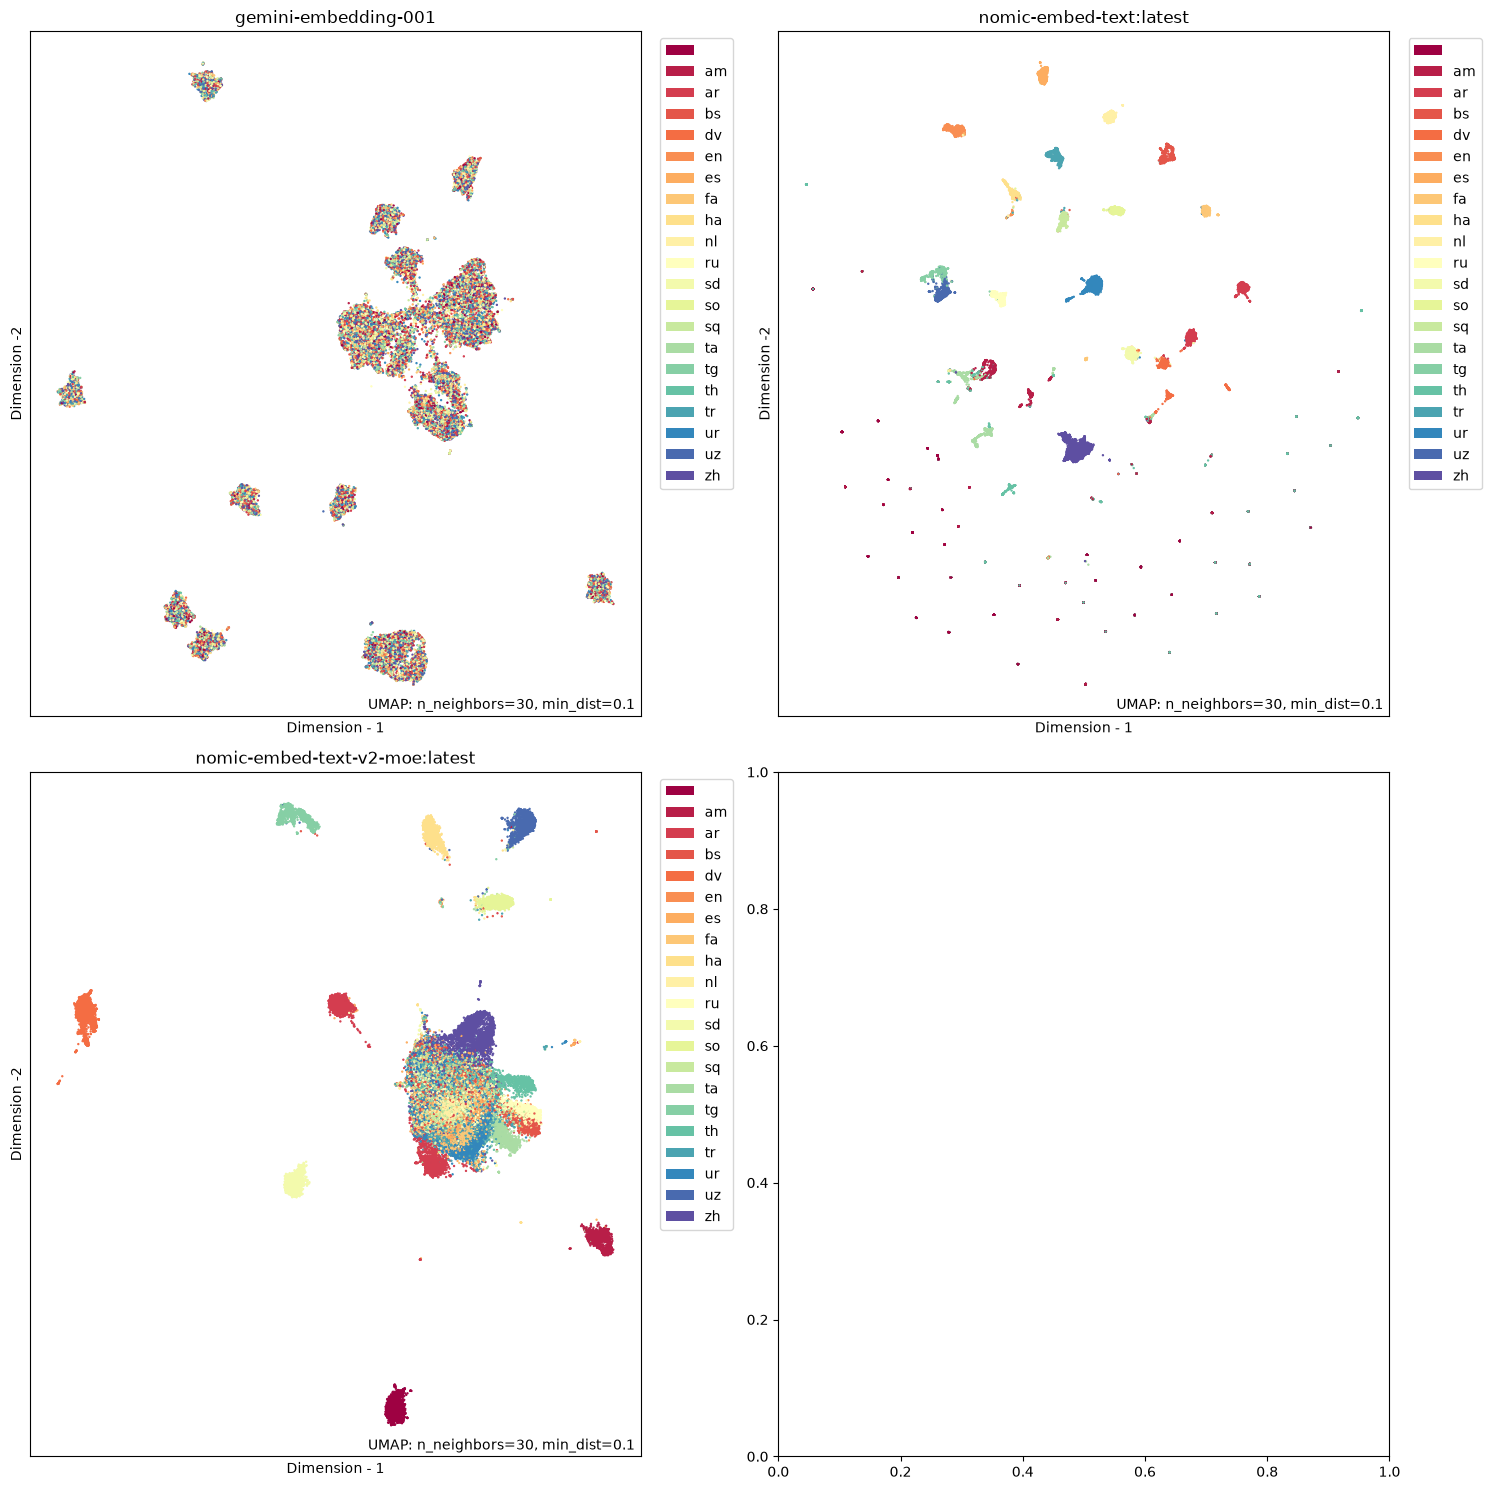
The projected data shows distinct clusters that are comprised primarily of one main language. The colours correspond to the actual language of the text for two of the vectorisers i.e from eyeball instruction.
tar_encoder = {}for c in collections: tar_encoder[c] = LabelEncoder() language_values = samples[c].language.fillna("n/a")# detect_language (used later for heur_lang) can return '' when no candidate# clears MIN_CONFIDENCE, even though no ground-truth row is ever ''. Include# it as a known class up front so transform() never hits an unseen label. tar_encoder[c].fit(pd.concat([language_values, pd.Series([''])], ignore_index=True)) target = tar_encoder[c].transform(language_values) samples[c]['target_idx'] = pd.Series(target)
Code
knn_clf = {}for c in collections: knn_clf[c] = fit_knn_classifier(dim_red[c],samples[c].loc[train_flag[c],'target_idx'],**knn_params)
Code
lg_pred_mdl = {}
for c in collections:
    lg_pred_mdl[c] = build_pred_pipeline(umap_model[c],knn_clf[c])
Sat Sep 12 17:27:23 2026 Building hub-based search tree
Sat Sep 12 17:27:31 2026 Forward diversification reduced edges from 1266540 to 420081
Sat Sep 12 17:27:34 2026 Reverse diversification reduced edges from 420081 to 420081
Sat Sep 12 17:27:36 2026 Degree pruning reduced edges from 481994 to 481994
Sat Sep 12 17:27:36 2026 Resorting data and graph based on tree order
Sat Sep 12 17:27:36 2026 Building and compiling search function
    completed  0  /  100 epochs
    completed  10  /  100 epochs
    completed  20  /  100 epochs
    completed  30  /  100 epochs
    completed  40  /  100 epochs
    completed  50  /  100 epochs
    completed  60  /  100 epochs
    completed  70  /  100 epochs
    completed  80  /  100 epochs
    completed  90  /  100 epochs
Sat Sep 12 17:27:48 2026 Building hub-based search tree
Sat Sep 12 17:27:48 2026 Forward diversification reduced edges from 1266540 to 424760
Sat Sep 12 17:27:48 2026 Reverse diversification reduced edges from 424760 to 424760
Sat Sep 12 17:27:49 2026 Degree pruning reduced edges from 532108 to 532083
Sat Sep 12 17:27:49 2026 Resorting data and graph based on tree order
Sat Sep 12 17:27:49 2026 Building and compiling search function
    completed  0  /  100 epochs
    completed  10  /  100 epochs
    completed  20  /  100 epochs
    completed  30  /  100 epochs
    completed  40  /  100 epochs
    completed  50  /  100 epochs
    completed  60  /  100 epochs
    completed  70  /  100 epochs
    completed  80  /  100 epochs
    completed  90  /  100 epochs
Sat Sep 12 17:28:06 2026 Building hub-based search tree
Sat Sep 12 17:28:07 2026 Forward diversification reduced edges from 1266540 to 446230
Sat Sep 12 17:28:07 2026 Reverse diversification reduced edges from 446230 to 446230
Sat Sep 12 17:28:07 2026 Degree pruning reduced edges from 538130 to 537820
Sat Sep 12 17:28:07 2026 Resorting data and graph based on tree order
Sat Sep 12 17:28:07 2026 Building and compiling search function
    completed  0  /  100 epochs
    completed  10  /  100 epochs
    completed  20  /  100 epochs
    completed  30  /  100 epochs
    completed  40  /  100 epochs
    completed  50  /  100 epochs
    completed  60  /  100 epochs
    completed  70  /  100 epochs
    completed  80  /  100 epochs
    completed  90  /  100 epochs
4.0 Results
4.1 Performance of Word Embeddings in Language Identification
The performance of the umap+knn-classification approach on all three collections was assessed using Mutual Information, Recall and Precision. nomic-embed-text:latest achieved the best performance followed by nomic-embed-text-v2-moe:latest. This is surprising particularly because nomic-embed-text:latest was developed primarily for English en.
- In terms of performance, the heuristic approach which is described fully in Section 6.1 achieved comparable (or better) recall and precision to the LLMs across all languages i.e. judging by the quantiles of distribution of recall and precision. It is however possible that a neural network trained on the embeddings would reveal a different result. It is also likely that a using a larger and more diverse dataset will show an entirely different pattern and this is a subject of further exploration. - The heuristic approach is also more informative about the languages than the LLMs. This is shown by the mutual information (MI) between the languages and the language predicted by the heuristic. - The detailed MI, recall, and precision obtained for each approach by each language is provided in Section 6.2
Horses for Courses: In certain situations, the least sophisticated approach is the most suitable. For instance, the heuristic approach that uses regular expressions for language detection could be more suitable for detecting languages than LLM based word representations.
5.1 Next Steps
Although the performance of the heuristic is explainable i.e. it is largely based on the scripts used in the text, it is unclear whether this is the same for the LLMs.
6.0 Appendix
6.1 Heuristic Language Detection
    flowchart TD
    A["detect_language(e)"] --> B["NFC-normalise text"]
    B --> C["Count chars per script block<br/>(Latin, Arabic, Cyrillic,<br/>Ethiopic, Thaana, Tamil, Thai, CJK)"]
    C --> D{"Any script<br/>chars found?"}
    D -->|no| UND(["main_language = ''"]):::und

    D -->|"yes: take dominant script"| E{"Script type?"}

    %% ---- Stage 1: unique scripts decided outright ----
    E -->|Ethiopic| U1(["am"]):::win
    E -->|Thaana| U2(["dv"]):::win
    E -->|Tamil| U3(["ta"]):::win
    E -->|Thai| U4(["th"]):::win
    E -->|CJK| U5(["zh"]):::win

    %% ---- Stage 2: shared scripts need disambiguation ----
    E -->|Arabic| AR["Score on EXCLUSIVE markers only"]
    E -->|Cyrillic| CY["Score on EXCLUSIVE markers only"]
    E -->|Latin| LA["Score on exclusive letters<br/>+ digraphs + stopwords"]

    AR --> AR1{"priority check"}
    AR1 -->|"Urdu retroflex / ye-barree"| ARu(["ur"])
    AR1 -->|"Sindhi implosives"| ARs(["sd"])
    AR1 -->|"Persian p/ch/zh/g (no ur,sd)"| ARf(["fa"])
    AR1 -->|"else Arabic kaf/ye / fallback"| ARa(["ar"])

    CY --> CY1{"exclusive Cyrillic marks"}
    CY1 -->|"Tajik ii/uu/j"| CYt(["tg"])
    CY1 -->|"Uzbek o-breve"| CYu(["uz"])
    CY1 -->|"Serbian dje/lje/nje"| CYb(["bs"])
    CY1 -->|"else / fallback"| CYr(["ru"])

    LA --> LA1["Per-language score:<br/>char x3, digraph x1, stopword x2"]
    LA1 --> LA2{"argmax<br/>(en,es,nl,sq,tr,bs,ha,so,uz)"}
    LA2 --> LAout(["best Latin lang"])

    %% ---- Final threshold ----
    ARu & ARs & ARf & ARa & CYt & CYu & CYb & CYr & LAout --> T{"best score >=<br/>MIN_CONFIDENCE?"}
    T -->|yes| WIN(["main_language = best"]):::win
    T -->|no| UND

    classDef win fill:#dcfce7,stroke:#16a34a,color:#14532d;
    classDef und fill:#fee2e2,stroke:#dc2626,color:#7f1d1d;
Here’s what each node in the diagram represents:
A — detect_language(e): entry point; takes one text string.
B — NFC-normalise: Unicode-normalises the text so composed/decomposed forms of the same character count identically.
C — Count chars per script block: tallies how many characters fall in each script range (Latin, Arabic, Cyrillic, Ethiopic, Thaana, Tamil, Thai, CJK). This is the single measurement that drives routing.
D — Any script chars found?: guards against empty/numeric/punctuation-only input. If nothing matches, the string is unclassifiable → '' (empty string).
E — Script type?: picks the dominant script (highest count from C) and branches on it. This is the key move — decide the script once, then only consider languages that use it.
U1–U5 — am / dv / ta / th / zh: the five languages with an exclusive script (Ethiopic, Thaana, Tamil, Thai, CJK). Script alone identifies them, so they’re returned immediately with no further scoring.
AR / CY / LA — “score on exclusive markers”: the three shared-script buckets. Each scores candidate languages only on features that differ between them — never on the shared range that caused the original collisions.
AR1 (Arabic priority check) → ur / sd / fa / ar: checks distinctive letters in priority order — Urdu retroflexes/yeh-barree first, then Sindhi implosives, then Persian consonants (only if no Urdu/Sindhi marks), else Standard Arabic or fallback.
CY1 (Cyrillic marks) → tg / uz / bs / ru: routes on exclusive Cyrillic letters — Tajik (ӣ ӯ ҷ), Uzbek (ў), Serbian (ђ ј љ њ ћ џ) — defaulting to Russian when none appear.
LA1 — per-language score: for the nine Latin languages, adds up weighted evidence — exclusive letter ×3, digraph ×1, stopword ×2. Stopwords are what separate en/nl/so, which have no unique letters.
LA2 — argmax → best Latin lang: picks the highest-scoring Latin language.
T — best score ≥ MIN_CONFIDENCE?: final gate. Every shared-script branch funnels here; a winner that clears the threshold becomes main_language, otherwise the result is '' (empty string).
WIN / UND: the two terminal outcomes — a confident language code, or the unclassified bucket (main_language == '', the blank row in your recall table).